If you need enterprise stream processing, Apache Flink (Ververica) is the first tool to look at here. Listed starting prices: Apache Kafka (Confluent) from $385 a month. Databricks fits unified data, analytics, and AI; Apache Kafka (Confluent) fits unified live data streaming. Prices, free plans and limits for all 6 tools follow.
Choosing data streaming platforms usually comes down to price, fit and limits. This Ainotely guide sets 6 tools side by side on those three points, with the facts kept short and checkable.
Key takeaways
Apache Flink (Ververica) sits first on this list: enterprise stream processing.
StreamSets is the one to check for intelligent streaming data pipelines.
Apache Kafka (Confluent) has the lowest monthly starting price in this list: $385 per month.
What to know about Amazon Kinesis first: tied to AWS ecosystem.
Apache Flink (Ververica) is a good fit for enterprise stream processing. It suits teams with solid engineering skills who need fine-grained control over stream processing logic.
On top of that, Flink can be complicated to develop and operate, and it commonly needs dedicated expertise in stream processing concepts. No starting price is listed for Apache Flink (Ververica) here; confirm pricing on the vendor site. On free options: Not stated.
Databricks is a good fit for unified data, analytics, and AI. Databricks gives you a unified product for data, analytics, and AI, with a data-centric approach. Databricks is a wide product, and its streaming capabilities are part of a bigger ecosystem.
Trade-offs to know: Can be complicated to optimize.
So it may be more than needed for pure streaming use cases. From a buyer's view, optimizing performance and managing costs can need expertise. Choose Databricks when you want an integrated environment for streaming, analytics, and AI instead of a dedicated streaming service. This comparison lists no price for Databricks; ask the vendor. As for free access: Not stated.
Apache Kafka (Confluent) is built with unified live data streaming in mind. Apache Kafka, offered commercially by Confluent, is a unified data streaming system that lets you stream, link, process, govern, and query live data. It is aimed at organizations that require a resilient and open foundation for event-driven applications, data pipelines, and live analytics.
Where it shines: Capable ecosystem for live data.
Kafka can be complicated to operate, particularly when self-managed, and needs skilled engineers to manage scaling and monitoring. The system supports a wide set of use cases, from messaging to stream processing, and suits teams looking for a mature ecosystem with solid community support. Price to start with Apache Kafka (Confluent): $385 per month. Apache Kafka (Confluent) includes a free tier.
Trade-offs to know: Needs expertise to tune for scale.
Amazon Kinesis is designed for AWS-native streaming data pipelines. Amazon Kinesis is a managed streaming data service on AWS that lets you collect, process, and analyze live data.
What to check first: Tied to AWS ecosystem.
Teams already using AWS will find it integrates well with other AWS services, making it a natural choice for building real-time pipelines without managing infrastructure. No starting price is listed for Amazon Kinesis here; confirm pricing on the vendor site. Amazon Kinesis has a free plan.
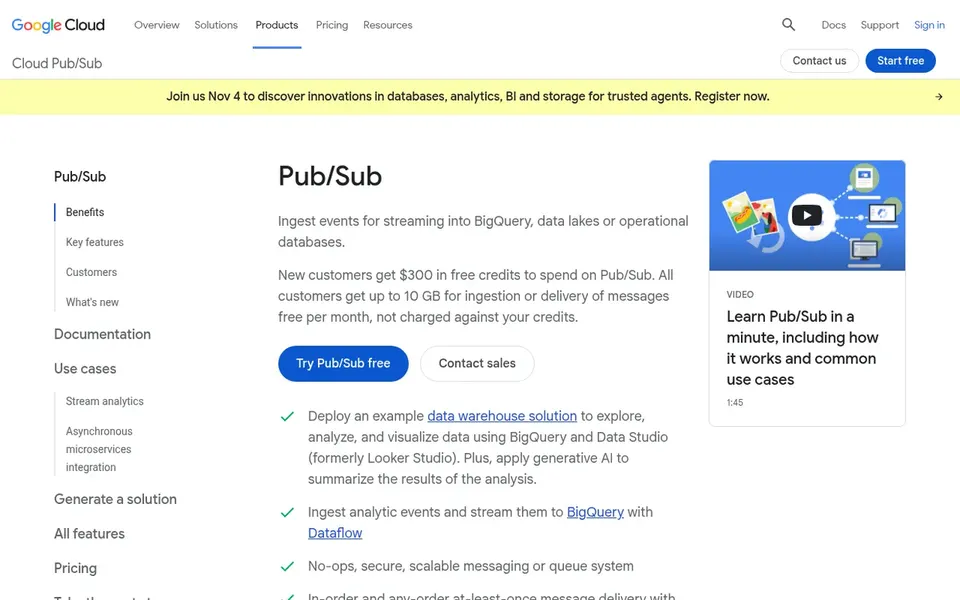
Google Cloud Pub/Sub is aimed squarely at GCP integration and event ingestion. Google Cloud Pub/Sub is a messaging and event ingestion service that streams data to BigQuery, data lakes, and databases. Pub/Sub is primarily an ingestion and messaging service, so complicated stream processing may need extra tools like Dataflow.
In practice, teams on Google Cloud can use Pub/Sub to build live pipelines that feed analytics and storage systems. For everyday use, choose Pub/Sub when you need steady event ingestion and are building on Google Cloud. Check the vendor site for Google Cloud Pub/Sub pricing; none is listed in this comparison. Trial and free access: Not stated.
The main drawbacks: Most useful for Google Cloud environments.
StreamSets makes the most sense for intelligent streaming data pipelines. IBM StreamSets is a system for building solid and intelligent streaming data pipelines to enhance live decision-making and mitigate risks associated with data flow. It is made for organizations that require to run complicated data flows across several sources and targets, with a focus on reliability and governance.
On top of that, StreamSets can fit teams looking for a pipeline-centric approach to streaming data integration. Also, consider StreamSets when you have to build and manage streaming pipelines with an emphasis on data flow reliability and risk mitigation. This comparison lists no price for StreamSets; ask the vendor. Free options: Not stated.
The main drawbacks: May need integration with other tools for full processing.
Confirm the entry price on the vendor page. For Apache Flink (Ververica), Databricks, Amazon Kinesis and others that means a quote rather than a fixed price.
Check what the free option really includes: Apache Kafka (Confluent) and Amazon Kinesis offer a free plan, and usage caps differ.
Before choosing Apache Flink (Ververica), weigh its main limit: needs specialized expertise.
Look at which plan of Databricks unlocks the features you need; entry tiers are often cut down.
Check the integration list for Google Cloud Pub/Sub against the tools you run today, and note which ones need a higher plan.
How we picked
Ainotely used vendor pricing pages and product documentation as the base, then compared plans, free access and documented limits for 6 tools. Seat minimums, billing terms and add-ons can move the real cost, so the starting prices here are a guide and not a quote. The order reflects how well each tool fits the most common buying scenario for data streaming platforms, then price clarity, then free plan access. It is a starting point, not a verdict.
Every price and plan detail on this page comes from the vendors’ own websites. We did not run hands-on tests unless the text says so, and we do not publish star ratings or review scores. See how we score and our disclosure.
Keep your shortlist in one place
Paste prices, trial dates and notes from this guide into Ainotely, our AI note app. It files them into a topic and pulls out tasks like “cancel trial by Friday”. Free 7-day trial, no card needed.
Which options for data streaming platforms have a free plan?
Apache Kafka (Confluent) and Amazon Kinesis offer a free plan in this list. Free plans usually cap users, projects or features, so check the limits on the vendor page.
Can I try these options before paying?
Often, yes. Apache Kafka (Confluent) and Amazon Kinesis have a free plan. Use your own data and a real task during the test, and check what the free tier or trial limits before you rely on it.
How do I choose between stream processing and data integration tools?
Data integration tools like NiFi and StreamSets focus on moving and transforming data between systems. Your choice relies on whether you need live analytics or dependable data flow management.
What is the cheapest option for data streaming platforms in this list?
On published monthly entry prices, Apache Kafka (Confluent) is the lowest here at $385 per month. Entry price is only part of the cost, because seats, add-ons and billing terms can change the total.
Do these tools publish their prices?
Not all of them. Apache Flink (Ververica), Databricks, Amazon Kinesis and others publish no starting price, so expect a quote request for those. The rest, Apache Kafka (Confluent) included, show a starting price, though seats and billing terms still change the final cost.
Which streaming product is a good match for AWS users?
Apache Flink (Ververica) comes first here and is built for enterprise stream processing. Buyers with other needs may prefer Databricks (for unified data, analytics, and AI) or Apache Kafka (Confluent) (for unified live data streaming). Compare costs and limits first.