Best Frontend Cloud Logging Tools in 2026: 7 Options Compared

- 1
 LogRocketsession replay plus logsVisit
- 2
 Sentryerror tracking across the stackVisit
- 3
 Datadog Real User Monitoringfrontend monitoring at scaleVisit
- 4
 Better Stacklogs and monitoring on a budgetVisit
- 5
 Honeybadgersimple error and log monitoringVisit
- LogRocket is our pick for frontend teams because it pairs session replay with console logs and network data.
- Sentry suits teams that want error tracking across frontend and backend in one place.
- Better Stack and Honeybadger are strong, lower-cost options for smaller teams.
- Watch event volume pricing closely, since logging costs rise fast on high-traffic sites.
Quick comparison
| Product | Ideal for | Price from | Free version | |
|---|---|---|---|---|
| LogRocket | session replay plus logs | See website | Free trial | Visit |
| Sentry | error tracking across the stack | See website | Yes | Visit |
| Datadog Real User Monitoring | frontend monitoring at scale | See website | Free trial | Visit |
| Better Stack | logs and monitoring on a budget | See website | Yes | Visit |
| Honeybadger | simple error and log monitoring | See website | Free trial | Visit |
 Raygun | error and performance monitoring | See website | Free trial | Visit |
 Rollbar | error tracking for developers | See website | Yes | Visit |
The best frontend cloud logging tools
We compared official feature pages, pricing pages, and public documentation for frontend cloud logging tools that work in October 2026. Our pick for most frontend teams is LogRocket, because replay plus logs shortens debugging, but error-first and budget options below deserve a look too.
LogRocket
Ideal for: session replay plus logs
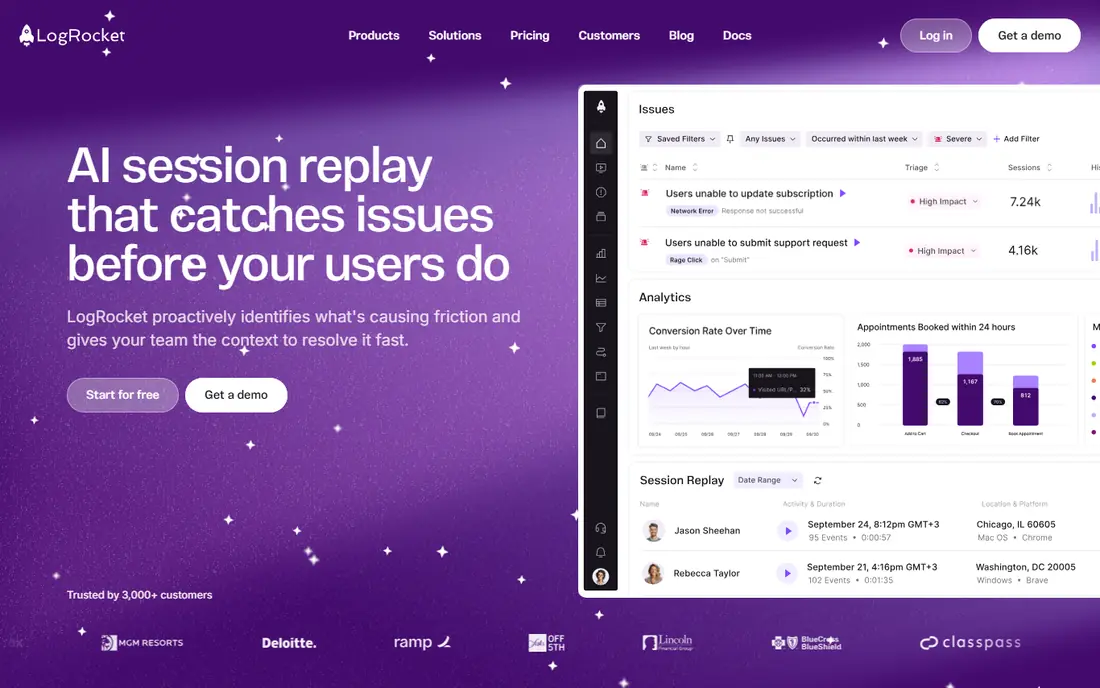
LogRocket records user sessions alongside console logs and network activity for frontend debugging. Its strength is context: replay shows the bug as the user saw it, not just as a stack trace. Support quality matters when something breaks, so read the help pages and the refund or cancellation terms before paying. Note which features sit behind higher tiers, because the headline plan rarely includes everything shown on the marketing page.
The catch is session-based pricing, which needs careful volume estimates on busy sites. Read the privacy policy for any product that holds personal or business data, and confirm who can see that data and how long it is kept.
Our view: if session replay plus logs is your main need, this option deserves a trial, with the trade-offs above kept in mind. Set a reminder to review the plan after the first month, when real usage shows whether the tier you picked still fits. A clean export path matters, so confirm you can take your data out in a usable format if you later switch.
- Session replay with logs and network data
- Frontend performance views
- Issue search
- Pricing scales with sessions
- Can be costly at high traffic
Sentry
Ideal for: error tracking across the stack
Sentry groups frontend and backend errors so teams can prioritise real crashes over noise. Its strength is breadth: one tool covers web, mobile, and server errors with shared context. Watch for limits that only appear at scale, such as seats, projects, scans, or exports, since those decide the real monthly cost. If your team will use it daily, get one or two colleagues to try the same task in it and compare notes before you choose.
The catch is configuration, since getting the most from it takes time on grouping and alerts. A clean export path matters, so confirm you can take your data out in a usable format if you later switch.
Our view: this option is a strong candidate when error tracking across the stack matters most, provided the limits above fit your budget. If you rely on it for work, confirm uptime, backup, and account recovery options before moving anything important into it. Check the pricing page before you commit, since plans and limits change and the page you see at signup is the one that counts.
- Strong error grouping
- Frontend and backend coverage
- Wide SDK range
- Session replay is an add-on area
- Event volume pricing needs care
Datadog Real User Monitoring
Ideal for: frontend monitoring at scale

Datadog Real User Monitoring tracks frontend performance and user sessions inside the wider Datadog platform. Its strength is linkage: frontend issues connect to backend traces and infrastructure data. Compare at least two options on the same task, using the same sample project or data, so the comparison stays honest. Check the pricing page before you commit, since plans and limits change and the page you see at signup is the one that counts.
The catch is scope and cost, since small teams may not need the full observability platform. Note which features sit behind higher tiers, because the headline plan rarely includes everything shown on the marketing page.
Our view: shortlist this option if frontend monitoring at scale is what you are buying for, and compare it head to head with one other option here. Look at how it handles your existing tools, because a product that fits your current setup saves more time than one with a longer feature list. If your team will use it daily, get one or two colleagues to try the same task in it and compare notes before you choose.
- Real user monitoring
- Session replay
- Links to backend traces and logs
- Enterprise pricing and platform breadth may overwhelm small teams
Better Stack
Ideal for: logs and monitoring on a budget
Better Stack combines log management with uptime monitoring at prices small teams can follow. Its strength is value and clarity, with pricing that is easier to model than many rivals. Check the pricing page before you commit, since plans and limits change and the page you see at signup is the one that counts. A clean export path matters, so confirm you can take your data out in a usable format if you later switch.
The catch is focus: teams wanting deep session replay should compare it with LogRocket first. A short trial or a free tier, where one exists, tells you more in a week than any feature list can.
Our view: this option earns its place here for buyers who put logs and monitoring on a budget first, and it is worth a close look before you decide. If your team will use it daily, get one or two colleagues to try the same task in it and compare notes before you choose. Note which features sit behind higher tiers, because the headline plan rarely includes everything shown on the marketing page.
- Log management
- Uptime monitoring
- Clear pricing pages
- Frontend replay is not its main focus
- Smaller ecosystem than large rivals
Honeybadger
Ideal for: simple error and log monitoring
Honeybadger tracks errors, logs, and uptime with a setup that small teams can finish quickly. Its strength is simplicity: you get the core debugging views without a long onboarding. Support quality matters when something breaks, so read the help pages and the refund or cancellation terms before paying. Look at how it handles your existing tools, because a product that fits your current setup saves more time than one with a longer feature list.
The catch is advanced needs, since large teams may want deeper replay or analytics. Read the privacy policy for any product that holds personal or business data, and confirm who can see that data and how long it is kept.
Our view: if simple error and log monitoring is your main need, this option deserves a trial, with the trade-offs above kept in mind. Set a reminder to review the plan after the first month, when real usage shows whether the tier you picked still fits. Support quality matters when something breaks, so read the help pages and the refund or cancellation terms before paying.
- Error tracking
- Log management
- Uptime checks
- Simple setup
- Fewer advanced replay features
- Smaller integration list
Raygun
Ideal for: error and performance monitoring
Raygun covers crash reporting and real user monitoring for web and mobile apps. Its strength is pairing crash data with performance views, so teams see both failures and slowness. Watch for limits that only appear at scale, such as seats, projects, scans, or exports, since those decide the real monthly cost. Compare at least two options on the same task, using the same sample project or data, so the comparison stays honest.
The catch is plan structure, since different monitoring areas can sit on different tiers. A clean export path matters, so confirm you can take your data out in a usable format if you later switch.
Our view: this option is a strong candidate when error and performance monitoring matters most, provided the limits above fit your budget. If you rely on it for work, confirm uptime, backup, and account recovery options before moving anything important into it. Set a reminder to review the plan after the first month, when real usage shows whether the tier you picked still fits.
- Crash reporting
- Real user monitoring
- Deployment tracking
- Pricing varies by product area
- Platform learning curve
Rollbar
Ideal for: error tracking for developers
Rollbar alerts developers to errors in real time and groups them for faster fixes. Its strength is speed of alerting, which helps teams catch regressions soon after a deploy. Compare at least two options on the same task, using the same sample project or data, so the comparison stays honest. Read the privacy policy for any product that holds personal or business data, and confirm who can see that data and how long it is kept.
The catch is scope: it is error-first, so teams wanting full session replay need another tool. Note which features sit behind higher tiers, because the headline plan rarely includes everything shown on the marketing page.
Our view: shortlist this option if error tracking for developers is what you are buying for, and compare it head to head with one other option here. Look at how it handles your existing tools, because a product that fits your current setup saves more time than one with a longer feature list. A short trial or a free tier, where one exists, tells you more in a week than any feature list can.
- Real-time error alerts
- Grouping and workflow tools
- Broad language support
- Frontend replay is limited
- Free tier caps events
How we picked these
We compared official feature pages, pricing pages, and public documentation for each tool. We looked for frontend log capture, session replay, error grouping, search, alerting, integrations, and volume-based pricing. We did not run hands-on tests.
What to check before choosing a frontend logging tool
Start with what you need to debug. Session replay helps for user-reported bugs, while error grouping helps for crashes at scale, and some teams need both.
Check data and privacy controls. Frontend logs can capture personal data, so confirm masking, retention, and region options before shipping to production.
Model your volume before buying. Estimate monthly sessions and errors, then compare tiers, since overage pricing often decides the real cost.
Frequently asked questions
What is frontend cloud logging?
It captures browser errors, console logs, network requests, and user actions, then stores them in the cloud for search and debugging. Teams use it to reproduce bugs without asking users for screenshots.
Do I need session replay as well as logs?
Logs show what happened in code, while replay shows what the user saw and did. Together they cut guesswork, but replay adds cost and privacy duties, so smaller teams may start with logs alone.
How much do frontend logging tools cost?
Many charge by sessions or events, with free tiers for small projects. High-traffic sites should model volume carefully and check overage rates.
Can frontend logging capture personal data?
Yes, if forms or URLs contain personal details, so use masking and data controls. Review each vendor privacy policy and your own legal duties before enabling full capture.