Best open source mlops platforms in 2026: 8 Options Compared

- Open-source MLOps tools trade vendor support for control, and setup effort varies enormously.
- Experiment tracking, pipelines and serving are different jobs, so most teams combine two or three tools.
- Check community activity and release pace before you build on a project.
Quick comparison
| Product | Ideal for | Price from | Free version | |
|---|---|---|---|---|
 MLflow | teams needing experiment tracking and model registry | Free | Yes | Visit |
 Kubeflow | teams running ML on Kubernetes at scale | Free | Yes | Visit |
 Metaflow | data scientists wanting Python-friendly pipelines | Free | Yes | Visit |
 Apache Airflow | teams orchestrating data and ML workflows | Free | Yes | Visit |
 DVC | teams versioning data and models with Git | Free | Yes | Visit |
 ZenML | teams wanting portable ML pipelines | Free | Yes | Visit |
 Flyte | teams running large-scale ML workflows | Free | Yes | Visit |
 Feast | teams needing a feature store for ML | Free | Yes | Visit |
The best best open source mlops platforms
We compared official feature pages, pricing, app store listings, privacy policies and public reviews to build this list of best open source mlops platforms. Our pick for most people is listed first in each section below, but the right choice depends on your budget, team size and must-have features, so read the strengths and limits for each option before you decide.
MLflow
Ideal for: teams needing experiment tracking and model registry
For readers weighing this option, the story starts with fit. MLflow is the default open-source pick for experiment tracking and model registry, with wide framework support. In practice, that means you should judge it on the job you need done most, not on the longest feature list, since a tool that fits your daily work beats a broader tool you rarely open. We also weighed pricing honesty, support options and how the product handles your data, because those factors shape the experience long after the first week.
The catch is pipelines, since orchestration is lighter than in dedicated pipeline tools. That trade-off is normal, since every product on this list gives up something to excel at its main job. Before you commit, use the free plan or trial with a real task from your own work, check the export and cancellation terms, and confirm the plan you need includes the features described here, since vendors move features between tiers from time to time.
- Open source
- Experiment tracking
- Model registry
- Pipeline orchestration is lighter than rivals
- Self-hosting needs care
Kubeflow
Ideal for: teams running ML on Kubernetes at scale
This one earns its place for a clear reason. Kubeflow brings ML workflows to Kubernetes at scale, with pipelines, notebooks and serving components. In practice, that means you should judge it on the job you need done most, not on the longest feature list, since a tool that fits your daily work beats a broader tool you rarely open. We also weighed pricing honesty, support options and how the product handles your data, because those factors shape the experience long after the first week.
The catch is complexity, since setup and maintenance need real Kubernetes skills. That trade-off is normal, since every product on this list gives up something to excel at its main job. Before you commit, use the free plan or trial with a real task from your own work, check the export and cancellation terms, and confirm the plan you need includes the features described here, since vendors move features between tiers from time to time.
- Open source
- Kubernetes-native pipelines
- Notebooks and serving
- Complex setup
- Needs Kubernetes expertise
Metaflow
Ideal for: data scientists wanting Python-friendly pipelines
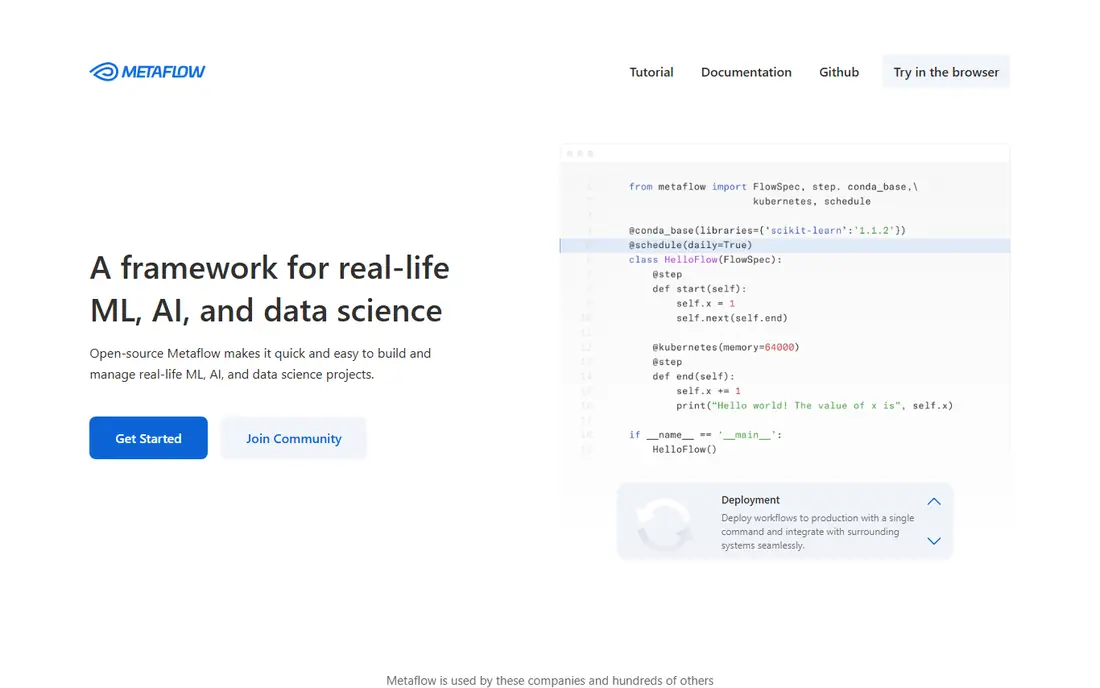
Here is where this option stands out from the rest of the list. Metaflow, originally from Netflix, lets data scientists write pipelines in plain Python and run them locally or in the cloud. In practice, that means you should judge it on the job you need done most, not on the longest feature list, since a tool that fits your daily work beats a broader tool you rarely open. We also weighed pricing honesty, support options and how the product handles your data, because those factors shape the experience long after the first week.
The catch is scale tooling, since Kubernetes-native depth is lighter than Kubeflow. That trade-off is normal, since every product on this list gives up something to excel at its main job. Before you commit, use the free plan or trial with a real task from your own work, check the export and cancellation terms, and confirm the plan you need includes the features described here, since vendors move features between tiers from time to time.
- Open source
- Python-first flows
- Local and cloud runs
- Kubernetes-native features are lighter
- Smaller ecosystem than Kubeflow
Apache Airflow
Ideal for: teams orchestrating data and ML workflows
Consider this option if its strengths match your main need. Apache Airflow is the mature orchestration choice, with a large community and scheduling that many data teams already know. In practice, that means you should judge it on the job you need done most, not on the longest feature list, since a tool that fits your daily work beats a broader tool you rarely open. We also weighed pricing honesty, support options and how the product handles your data, because those factors shape the experience long after the first week.
The catch is ML specificity, since ML tracking and serving need companion tools. That trade-off is normal, since every product on this list gives up something to excel at its main job. Before you commit, use the free plan or trial with a real task from your own work, check the export and cancellation terms, and confirm the plan you need includes the features described here, since vendors move features between tiers from time to time.
- Open source
- Mature orchestration
- Large community
- Not ML-specific
- ML features need extra work
DVC
Ideal for: teams versioning data and models with Git
This entry suits a narrower audience, and that focus is its strength. DVC versions data and models alongside Git code, which makes ML experiments reproducible in a familiar way. In practice, that means you should judge it on the job you need done most, not on the longest feature list, since a tool that fits your daily work beats a broader tool you rarely open. We also weighed pricing honesty, support options and how the product handles your data, because those factors shape the experience long after the first week.
The catch is workflow, since it works best for teams already comfortable with Git. That trade-off is normal, since every product on this list gives up something to excel at its main job. Before you commit, use the free plan or trial with a real task from your own work, check the export and cancellation terms, and confirm the plan you need includes the features described here, since vendors move features between tiers from time to time.
- Open source
- Git-friendly data versioning
- Experiment tracking
- Learning curve
- Best with Git workflows
ZenML
Ideal for: teams wanting portable ML pipelines
On value alone, this option deserves a close look. ZenML abstracts pipelines from infrastructure, so the same pipeline can run on different orchestrators without rewrites. In practice, that means you should judge it on the job you need done most, not on the longest feature list, since a tool that fits your daily work beats a broader tool you rarely open. We also weighed pricing honesty, support options and how the product handles your data, because those factors shape the experience long after the first week.
The catch is community size, since it is smaller than MLflow and Airflow. That trade-off is normal, since every product on this list gives up something to excel at its main job. Before you commit, use the free plan or trial with a real task from your own work, check the export and cancellation terms, and confirm the plan you need includes the features described here, since vendors move features between tiers from time to time.
- Open source
- Portable stacks
- Pipeline abstraction
- Smaller community than MLflow
- Tracking depth varies
Flyte
Ideal for: teams running large-scale ML workflows
If you want a dependable choice, start here. Flyte, originally from Lyft, handles large-scale ML workflows with strong reproducibility and scheduling. In practice, that means you should judge it on the job you need done most, not on the longest feature list, since a tool that fits your daily work beats a broader tool you rarely open. We also weighed pricing honesty, support options and how the product handles your data, because those factors shape the experience long after the first week.
The catch is setup, since running it well needs platform engineering skills. That trade-off is normal, since every product on this list gives up something to excel at its main job. Before you commit, use the free plan or trial with a real task from your own work, check the export and cancellation terms, and confirm the plan you need includes the features described here, since vendors move features between tiers from time to time.
- Open source
- Scalable workflows
- Reproducibility
- Setup complexity
- Needs platform skills
Feast
Ideal for: teams needing a feature store for ML
The final entry rounds out the list with a different angle. Feast is the open-source feature store pick, serving consistent features for training and live prediction. In practice, that means you should judge it on the job you need done most, not on the longest feature list, since a tool that fits your daily work beats a broader tool you rarely open. We also weighed pricing honesty, support options and how the product handles your data, because those factors shape the experience long after the first week.
The catch is scope, since it covers features, not the whole ML lifecycle. That trade-off is normal, since every product on this list gives up something to excel at its main job. Before you commit, use the free plan or trial with a real task from your own work, check the export and cancellation terms, and confirm the plan you need includes the features described here, since vendors move features between tiers from time to time.
- Open source
- Feature store
- Online and offline serving
- Feature-store focus
- Needs companion tracking tools
How we picked these
We compared official feature pages, pricing pages, app store listings, privacy policies and public reviews for each product on this list, and we checked that each product exists and works today. We favoured products that fit the topic directly, offered clear pricing or a usable free tier, and showed an honest balance of strengths and limits. We did not claim hands-on testing we did not do, and where a price could not be verified we wrote See website rather than guessing.
We also mixed well-known leaders with strong smaller options, so the list is useful whether you want the safest default or a more specialised pick. If a product changed its pricing or features after our check, the vendor website is the final word, and we recommend confirming the plan details before you buy.
How to choose the right best open source mlops platforms
Map your lifecycle before you pick tools. If tracking is the gap, start with MLflow and DVC. If pipelines are the gap, compare Metaflow, ZenML, Airflow and Kubeflow by your Kubernetes skills and scale. If serving features consistently is the gap, add Feast. Pilot with one real model end to end, including retraining and rollback, before you standardise, since a tool that demos well may still fail on your deployment path.
Use the checklist below with your own shortlist, since it catches the problems that cause most regret after purchase.
- Fit first: does it solve your main job, or does it only look impressive in a demo.
- True cost: add up seats, add-ons, taxes and renewal prices, not just the headline monthly figure.
- Exit route: can you export your data and cancel without a long process or penalty.
- Support and privacy: check support hours, data handling and security practices before you rely on it daily.
Run a trial with real work, not sample data, and involve the people who will use the product every day. Their verdict after a week of real tasks tells you more than any feature table, including ours.
Frequently asked questions
What are the best open-source MLOps platforms?
MLflow leads for experiment tracking, Kubeflow leads for Kubernetes-scale pipelines, and Metaflow suits Python-first data scientists. Airflow leads for general orchestration, DVC for data versioning, and Feast for feature stores.
Is MLflow free?
Yes. MLflow is open source and free to self-host, though managed hosting and support cost money. Self-hosting needs your own infrastructure and maintenance, so budget engineering time alongside licence savings.
Do I need Kubernetes for MLOps?
Not always. Metaflow, MLflow and DVC work without Kubernetes, while Kubeflow and Flyte assume it. Choose Kubernetes-native tools only if you already run Kubernetes or need their scale.
What is the difference between MLflow and Kubeflow?
MLflow focuses on experiment tracking and model registry, while Kubeflow is a Kubernetes-native platform for pipelines, notebooks and serving. Many teams use both, with MLflow for tracking inside Kubeflow pipelines.
Can open-source MLOps replace managed platforms?
Yes, for teams with platform skills, but managed platforms save setup and maintenance time. Open source gives control and avoids lock-in, while managed tools suit teams that prefer support and faster setup.